Odaptos is an AI-driven interview and assessment platform focused on delivering intelligent candidate evaluation and conversational AI capabilities. As the platform evolved, Odaptos required a scalable and automated AI/ML infrastructure capable of supporting real-time AI interactions, semantic search, knowledge ingestion, and continuous AI model training on AWS.
The Challenge
Odaptos needed a centralized and scalable AI/ML platform to support growing AI workloads, knowledge retrieval systems, and future model training requirements. The existing architecture lacked a fully integrated MLOps framework capable of managing AI inference, vector-based retrieval, model hosting, and automated training pipelines in a secure and scalable manner.
Key challenges included:
Lack of centralized AI model hosting architecture
Limited automation for AI model training and deployment
No scalable semantic search and retrieval pipeline
Difficulty managing long-term AI context and embeddings
Need for secure and scalable AI-powered APIs
Lack of event-driven document ingestion and metadata extraction
Requirement for AI orchestration across multiple AWS services
Need for governance, version control, and rollback mechanisms for AI models
Why Futuralis
& AWS
Odaptos partnered with Futuralis because of its expertise in AWS AI/ML architectures, MLOps automation, serverless application development, and cloud-native AI infrastructure engineering.
AWS provided the managed AI and machine learning services required to build a scalable, automated, and secure AI ecosystem while minimizing infrastructure management overhead.
Futuralis designed a phased AI/ML transformation strategy focused on:
Real-time AI-powered backend orchestration
AI model hosting and lifecycle management
Retrieval-Augmented Generation (RAG) architecture
Semantic search and vector embedding pipelines
Automated SageMaker training pipelines
AI governance and model versioning
Event-driven automation and scalable AI workflows
Our Solution
The AWS-centered solution to meet PCI compliance included:
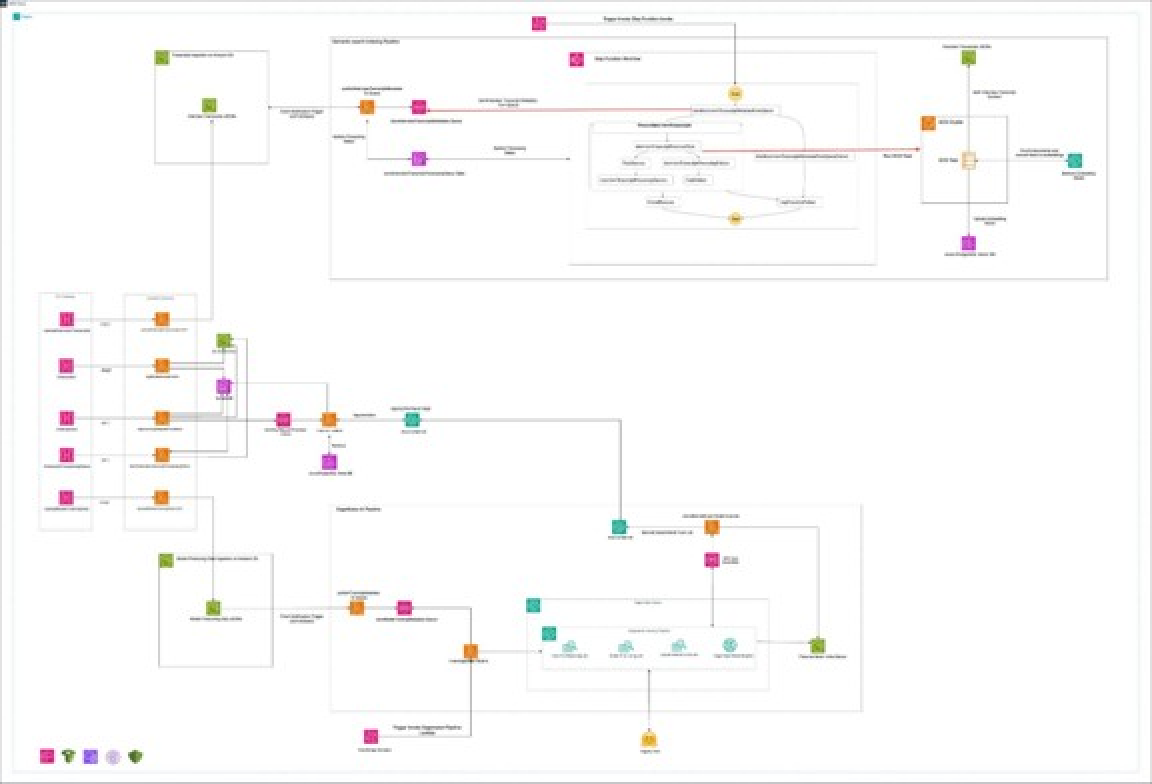
Futuralis designed and implemented a modern Generative AI and MLOps platform on AWS using Amazon Bedrock, SageMaker, Lambda, Aurora PostgreSQL with PGVector, ECS Fargate, and serverless event-driven workflows.
Phase 1 – Real-Time AI Backend Platform:
Implemented a serverless AI-powered backend using Amazon Bedrock Claude 3, API Gateway, AWS Lambda, DynamoDB, SQS, and Aurora PostgreSQL with PGVector
Developed REST APIs for AI interactions, session tracking, and contextual retrieval
Built CI/CD pipelines using Bitbucket for infrastructure and backend deployments
Implemented Infrastructure-as-Code using AWS CloudFormation
Configured secure networking, IAM policies, logging, and monitoring
Phase 2 – Knowledge Ingestion & Semantic Search:
Developed AI-powered document ingestion pipelines using Amazon S3, Amazon Textract, and SageMaker Processing Jobs
Built RAG-based semantic retrieval architecture using LangChain and Amazon Titan Embeddings
Implemented vector embedding storage using Aurora PostgreSQL with PGVector
Designed Step Functions and ECS Fargate workflows for transcript chunking, indexing, and retrieval
Enabled event-driven execution using Amazon EventBridge
Phase 3 – Automated MLOps & Fine-Tuning:
Implemented SageMaker Pipelines for preprocessing, training, evaluation, and deployment automation
Created model registry, approval workflows, rollback mechanisms, and model version tracking
Automated Bedrock model import workflows using Lambda and Systems Manager Parameter Store (SSM)
Enabled continuous fine-tuning and live model refresh without downtime
Built automated data ingestion workflows for transcripts and training datasets
The final architecture integrated AI inference, semantic search, RAG pipelines, automated model training, vector databases, and serverless APIs into a scalable end-to-end AI platform.
Context-aware AI responses using semantic retrieval
Continuous AI model training and optimization. Centralized AI model governance and versioning. Zero-downtime AI model deployment workflows.
Improved scalability for transcript ingestion and semantic search
Reduced operational overhead for AI model lifecycle management. Event-driven automation for AI pipelines and workflows.
Secure and enterprise-grade AI infrastructure using private networking and IAM controls
Cost-optimized architecture using serverless and pay-per-use services. Faster deployment and experimentation of AI capabilities across the Odaptos platform
MLOps automation is essential for scalable AI model lifecycle management. Vector databases and semantic retrieval significantly improve AI response quality. Event-driven architectures simplify AI workflow orchestration. Centralized model governance improves operational control and traceability. Serverless AI architectures reduce operational overhead and improve scalability. Retrieval-Augmented Generation (RAG) enhances contextual AI interactions. AWS managed AI services accelerate implementation and simplify operations. Continuous AI fine-tuning improves long-term model performance and business value
Ready to discover how Futuralis can elevate your cloud journey?
Get in touch today and let’s explore the full power of AWS together.